Businesses and researchers deal with enormous datasets every day. However, raw data alone rarely provides clear answers. This is where statistical analysis and data reconfiguration come into play. Together, these processes transform disorganized information into structured, meaningful insights.
Understanding these concepts is essential for anyone working with data, whether in business, research, or analytics. At Linkinfotech, we help organizations prepare and analyze their data so it translates into insights they can actually act on. In this guide, we’ll explain what statistical analysis and data reconfiguration mean, how they work together, and why they matter for accurate decision-making.
What Is Statistical Analysis?
Statistical analysis is the process of collecting, examining, and interpreting data to identify patterns, trends, and relationships. It helps organizations move beyond guesswork and make decisions backed by evidence.
Analysts typically use statistical methods to summarize large datasets and draw meaningful conclusions from them. Moreover, statistical analysis forms the foundation for nearly every data-driven decision made across industries, from healthcare to finance to marketing.
There are two primary types of statistical analysis: descriptive and inferential. Descriptive analysis summarizes existing data without concluding it. Inferential analysis, on the other hand, uses sample data to make predictions or generalizations about a larger population.
To perform these analyses accurately, professionals often rely on structured methodologies. If you’re new to the process, understanding how we analyze data provides a helpful starting point before exploring more advanced statistical techniques.
Turn Survey Data Into Business Decisions Faster
Technology-driven market research for faster, smarter insights.
What Is Data Reconfiguration?
Data reconfiguration refers to the process of rearranging, restructuring, and transforming raw data into a format suitable for analysis. Essentially, it prepares messy or inconsistent data so that statistical tools can process it accurately.
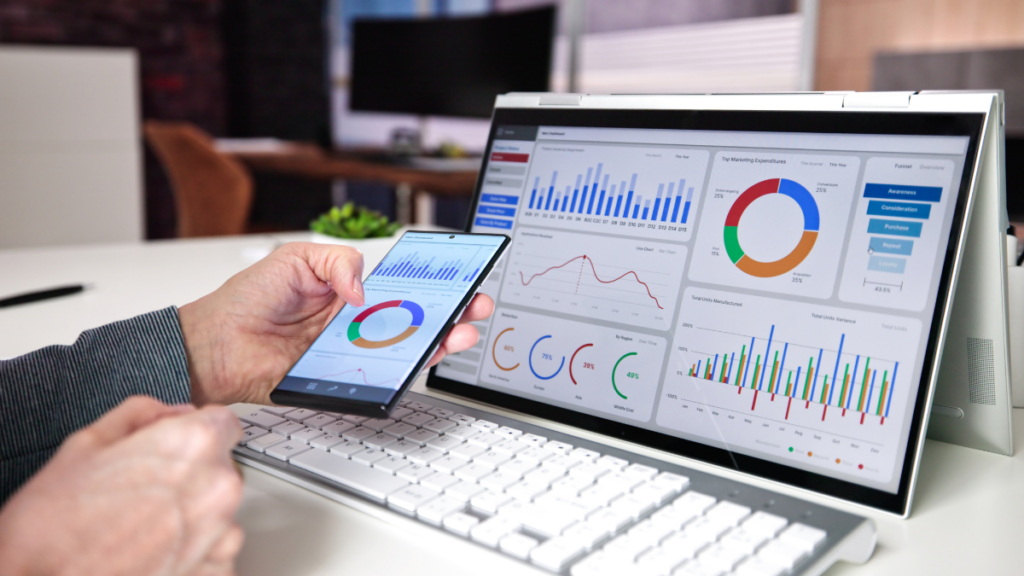
Unlike statistical analysis, which focuses on interpreting results, data reconfiguration focuses on preparation. This includes cleaning datasets, correcting errors, standardizing formats, and organizing variables logically.
Without proper reconfiguration, even the most sophisticated statistical models can produce misleading results. Therefore, this step is often considered just as important as the analysis itself. Analysts frequently document these changes while learning how to transform data in SPSS, which is a common technique used to reshape variables before running statistical tests.
How Statistical Analysis and Data Reconfiguration Work Together
Although these two processes serve different purposes, they’re deeply interconnected. Data reconfiguration typically happens first, ensuring the dataset is clean and structured. Statistical analysis then follows, extracting insights from that prepared data.
Think of it this way: reconfiguration builds the foundation, while analysis constructs meaning on top of it. Without a solid foundation, analytical conclusions become unreliable. Consequently, skipping proper data preparation often leads to inaccurate business decisions.
For example, when importing data from spreadsheets into statistical software, analysts often need to reformat variables first. This process, commonly explained through guides like moving data from Excel to SPSS, illustrates how reconfiguration directly supports accurate statistical modeling afterward.
The Data Reconfiguration Process Explained
Data reconfiguration typically follows several structured steps to ensure datasets are analysis-ready.
- Data cleaning – Removing duplicates, correcting errors, and standardizing formats.
- Handling missing values – Deciding whether to remove, replace, or estimate missing data points.
- Variable transformation – Converting data into formats suitable for specific statistical tests.
- Data restructuring – Reorganizing datasets from wide to long format, or vice versa.
- Validation checks – Confirming that reconfigured data aligns with expected values and ranges.
Missing data is one of the most common challenges analysts face. Learning how to delete missing data in SPSS ensures that incomplete records don’t distort statistical outcomes later in the process.
Types of Statistical Analysis Methods
Once data has been properly reconfigured, analysts apply various statistical methods depending on their research goals.
Descriptive Statistics
These summarize data using measures like mean, median, mode, and standard deviation. They provide a quick snapshot of dataset characteristics without drawing broader conclusions.
Inferential Statistics
This method uses sample data to make predictions about larger populations. Hypothesis testing, confidence intervals, and regression analysis all fall under this category.
Diagnostic Analysis
Diagnostic analysis examines why certain patterns occurred within a dataset. It often builds upon descriptive findings to identify underlying causes.
Predictive Analysis
This approach uses historical data to forecast future outcomes. Businesses widely use predictive statistical models for demand forecasting and risk assessment.
For those exploring these techniques in software environments, a solid SPSS tutorial for data analysis can help bridge the gap between statistical theory and practical application.
Why Data Reconfiguration Matters Before Analysis
Skipping proper data reconfiguration can significantly compromise research quality. Inconsistent formats, missing values, and duplicate entries often lead to skewed statistical results.
Furthermore, reconfigured data improves the efficiency of analysis itself. Clean, well-structured datasets allow statistical software to run calculations faster and more accurately. As a result, analysts spend less time troubleshooting errors and more time interpreting meaningful insights.
Data reconfiguration also plays a critical role in comparative studies. When merging multiple datasets from different sources, formats must align precisely. Without this step, statistical comparisons between datasets would produce unreliable or inconsistent conclusions.
Statistical Analysis vs. Data Analytics: Understanding the Difference
Many professionals confuse statistical analysis with broader data analytics practices. While related, these terms aren’t interchangeable.
Statistical analysis focuses specifically on applying mathematical techniques to interpret data and test hypotheses. Data analytics, however, encompasses a wider range of processes, including data visualization, business intelligence, and predictive modeling.
Understanding this distinction helps professionals apply the right approach for their specific goals. Our detailed comparison of data analysis vs data analytics breaks down these differences clearly for beginners entering the field.
Turn Complex Datasets Into Strategic Business Growth
Enterprise-grade data processing, statistical analysis, and customized tabulations to power your insights.
Common Tools Used for Statistical Analysis and Data Reconfiguration
Professionals rely on specialized software to handle both reconfiguration and analysis efficiently. Popular tools include:
- SPSS – Widely used for statistical testing and data transformation in academic and business research.
- R – A programming language favored for advanced statistical modelling.
- Python – Popular for combining data reconfiguration with machine learning applications.
- Excel – Commonly used for basic data cleaning before importing into specialized software.
- SAS – Frequently used in corporate and research environments for large-scale statistical analysis.
Choosing the right tool often depends on dataset size, complexity, and the specific statistical tests required. Exploring various data analysis tools can help professionals identify which platform best suits their workflow.
Real-World Applications of Statistical Analysis and Data Reconfiguration
These processes aren’t limited to academic research. Ultimately, they power decision-making across numerous industries.
- Healthcare – Reconfiguring patient data before analyzing treatment effectiveness.
- Marketing – Structuring survey responses before identifying consumer trends.
- Finance – Cleaning transactional data before running risk assessment models.
- Education – Organizing test score data before evaluating learning outcomes.
- Manufacturing – Reformatting sensor data before conducting quality control analysis.
In quantitative research specifically, proper data handling directly affects study validity. Reviewing best practices for data analysis and interpretation in quantitative research highlights just how essential reconfiguration is before drawing statistical conclusions.
Best Practices for Accurate Statistical Analysis
- Always clean and validate data before beginning analysis.
- Choose the correct statistical test based on your data type and research question.
- Document every reconfiguration step for transparency and reproducibility.
- Check for outliers that may distort statistical results.
- Present findings clearly using well-structured reports for stakeholders.
Following these practices ensures accuracy while making results easier for others to interpret and act upon. Once analysis is complete, presenting findings effectively matters just as much as the calculations themselves. Structuring results properly, similar to guidance found in how to make a data analysis report, helps ensure insights are communicated clearly to decision-makers.
Program Complex Questionnaires and Skip Logic
Expert survey scripting, advanced routing, and multi-language configurations for flawless data collections.
Conclusion
Statistical analysis and data reconfiguration work hand in hand to transform raw, disorganized data into reliable, actionable insights. While reconfiguration prepares and structures data, statistical analysis interprets it to reveal meaningful patterns and trends.
Businesses and researchers who invest time in proper data preparation consistently achieve more accurate, trustworthy results. As data volumes continue growing across industries, mastering both processes will remain essential for anyone working with numbers professionally.
Ultimately, strong statistical analysis begins with strong data reconfiguration. Together, they form the backbone of every credible, data-driven decision.
Frequently Asked Questions
Data reconfiguration focuses on cleaning and restructuring data, while statistical analysis focuses on interpreting that data to conclude.
Without proper reconfiguration, datasets may contain errors, missing values, or inconsistent formats that lead to inaccurate statistical results.
SPSS, R, Python, and SAS are among the most widely used tools, depending on the complexity of the dataset and analysis required.
Data cleaning is one part of the broader reconfiguration process, which also includes restructuring, transforming, and validating data.
No, skipping reconfiguration often leads to unreliable results, since raw, unorganized data can distort statistical calculations significantly.